Nota, for judges
Nota enters all three tracks. Each section below stands on its own: what to open, what it proves, and the rubric line it answers. Every link goes to live data, never to a mock-up.
Do this, you should see
| Do this | You should see | Rubric |
|---|---|---|
uv run nota judge | six PASS lines: every receipt identical, every citation read back, every Bitcoin proof and Sigstore Rekor entry verified | repeatability |
| Dashboard: Verify in this browser | verified here: your browser hashed the evidence, re-derived the receipt id and read every citation back | T1 repeatability |
| Same receipt: What did this decision rest on? | each input the rules read, removed in turn, and which ones block or resize the trade | T1 cause and effect |
| Same receipt: Change it and check (tamper) | refused: the edited evidence no longer hashes to the receipt | coping with failure |
| Drill: RYO down | failed sections kept as failed, values null, no trade | coping with failure |
| Scorecard | RYO's own plans settled on OKX candles, every miss counted | combining sources, T2 |
| Same receipt: Find the edge | the smallest move in each number (and in the judge's probability) that turns the trade into no trade, each row checkable with the what-if | T1 cause and effect |
uv run nota reproduce <id> | seven PASS lines for a receipt fetched from this public site: evidence hash, id, citations, anchor, sizing, Bitcoin proof, Rekor entry | repeatability |
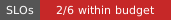
| Status | six objectives with error budgets counted from the ledger (two are spent while RYO's allowance is out, and say so), a spoken briefing, and how each token's belief moved | coping with failure, works for everyone |
| Model card | intended use, out of scope, factors and metrics, every number computed from the ledger | real thinking |
uv run nota verify-card | the Agent Card's Ed25519 signature: valid | T3 follows spec |
This site is public and read-only; the source repository is private to the judges.
uv run nota serve --demo serves every page here from the shipped ledger.
One minute, three clicks
- Open the dashboard. The newest receipt is already open: read its five-line summary, then press Verify replay to re-run the call from its stored evidence.
- Open the scorecard: its first paragraph says whether RYO's own verdict predicts how its trade plans end.
- Open the failure drill and press RYO down: the pipeline keeps missing values empty and refuses to trade.
Or check every claim on your own machine, with no key: uv sync, then uv run nota judge.
It replays every receipt, reads every citation back from its evidence, checks every Bitcoin proof against the stored
bytes, checks every receipt came from RYO, checks every receipt's Sigstore Rekor entry offline, and scans the git history for credentials: six PASS/FAIL lines in about 20 s.
uv run nota serve --demo serves this site from the shipped ledger.
The honest result so far
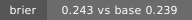
The council is not yet better than a coin flip. Over the 82 scored calls where the council met (as of 2026-11-10), the judge's Brier score is 0.243 (0.25 is always saying 50%; lower is better). That is why the code, not the model, pools the agents by their measured calibration, caps the model's confidence at the pooled council's, and checks every number in its prose against the evidence; live figures at /api/scores. Against always-0.5, persistence, RYO's verdict, the base rate and each single LLM on the same questions (Brier Index, head-to-head log scores with t intervals, leave-one-agent-out, the calls where Nota and RYO disagreed, cost): /scorecard and /api/benchmarks.
Found, measured, not yet adopted. A walk-forward recalibration, each call re-predicted by a fit on the calls
resolved before it, scores 0.233 against the raw 0.251 on 51 calls out of sample (it lost on the first 39). Its slope of 1.77
says the council is underconfident, and its intercept that prices fell more often than it said. The decision rules
adopt nothing from it until the scores are readable: 20 independent weeks, 15 so far (/api/scores →
recalibration).
What we say before you find it. On the 32 scored calls where both took a direction, the council agreed
with RYO's own call every time (both 63% right; /api/scores → vs_ryo): so far it has added
checks and sizing discipline to RYO's view, not a different view. The falsifier tally's "held" means "not proven
wrong": of 36 practice trades graded, 1 reached its target, 5 hit their stop and 30 touched neither
(falsifiers.trade_exits). And Murphy's decomposition puts the council's weakness in calibration: prices
rose in a third of those weeks while its stated chances sat near a half.
Tested, not only scored (/api/scores: paired_tests, reliability.bins[].consistency_90; /api/scorecard: multiple_testing). A Diebold-Mariano test, flipping the sign of whole token-weeks, of the judge against the base rate, 82 calls in 15 token-weeks: Brier difference +0.0046 (p = 0.9011), log score +0.0088 nats (p = 0.9087): no difference the data can tell from chance; against the prediction market, 69 calls in 12 token-weeks: Brier difference -0.0119 (p = 0.5908), log score -0.0244 nats (p = 0.5962): no difference the data can tell from chance. Broecker-Smith consistency bands: 3 of 3 reliability bins sit outside the 90% band a calibrated judge would land in (stated 0.35, happened 0.0, band 0.091-0.636; stated 0.502, happened 0.244, band 0.366-0.634; stated 0.651, happened 0.433, band 0.5-0.8). On the scorecard at 72 h, 0 of 10 tests (each contrast on two measures) are distinguishable one by one and 0 after a Benjamini-Hochberg false-discovery correction.
Every track (common 40)
| Rubric | Open this | What it shows |
|---|---|---|
| Combining sources · 20 | receipt 0d9469f115d1, Evidence provenance | Five RYO tools plus the independent checks (exchange prices, recomputed RSI/ATR, OKX positioning, DefiLlama liquidity, prediction markets, narrative voices, news) in one evidence pack, argued over by three agents and a judge. Code then holds the judge to the evidence: RYO's price must agree with the exchange median within 2%, and RYO's call limits the size (see a receipt's "Checked in code" card). |
| Coping with failure · 20 | 2ae531ec2c9b (RYO answered 401) and
c60acf3ba3b1 (RYO deep_analysis down for three days) |
The run still completes, records which section failed and why, and refuses to trade. A missing value stays
null; nothing is filled in. Settlement kept running through both; every lock attempted during the deep_analysis outage is counted as a ryo_unavailable line, none of them as a plan.
Or break it yourself: the failure drill injects twelve failures (RYO down, 401, deep_analysis missing,
rate limits, exchanges down, model down, partial answers, a prompt injection, edited evidence, a forged receipt, a restart mid-run, the practice book past its drawdown limit) into the real pipeline, offline, beside a healthy run.
How the pipeline coped, from the ledger (/api/resilience):
|
| SocialFi (sponsor theme) | /feed, /api/reputation | Public reasoning feed with each agent's stance and the dissent, X share links and receipt cards; backers and the
council's agents ranked on one hit-rate scale (unranked until 20 calls over 20 independent token-weeks); a public
watchlist and a profile per handle (/u/<handle>). Handles are unverified claims. |
Track 1 · Autonomous Agents
- Run it yourself. In the dashboard, "Run the council live" gathers fresh RYO evidence and convenes the council on any symbol (one to two minutes, capped per visitor).
- Agent vs agent. The feed marks every call where the agents split, names who dissented and quotes why; the reputation board scores those agents beside the humans who backed them.
- Proven wrong, or not. Every long or short states, before the fact, the price that would prove it wrong
(the trade's own stop, or the decision price at seven days), and is graded against it; the tally is at
/api/scores under
falsifiers, with how the held trades actually ended. - Verify in this browser. On any receipt, the evidence bytes are hashed by your own browser (Web Crypto), the receipt id is re-derived from that hash, and every citation is read back from the same bytes: every shipped receipt and every one of its citations pass, and nothing the server says about itself is trusted.
- Ask RYO again now. Any stored decision can be re-run on evidence gathered live, with every input and cited value shown then and now; the verdict stays fixed and no model is called.
- Challenge a call. On any receipt, change an evidence value the rules read or a rule itself (ATR multiples, minimum edge, risk) and see whether the decision holds; the model's verdict stays fixed.
- Chaos switch. "Run the council live" can force any one RYO tool to fail, as a 429 or an outage, while every other call is real.
- Real thinking (25). Open any receipt: each agent cites dotted paths into RYO's answer, and the value shown is read back out of the evidence, not retyped by the model. Citations to paths that do not exist are dropped in code, and since 2026-11-06 every number written in the agents' prose is looked up in the evidence too: one with no match is shown in red on the receipt.
- Cause and effect (20). The "Checked in code" card pools the agents' probabilities by their Brier weights, applies a stated rule, and says when the judge deviated; the trade's edge is the smaller of the two, so the model can lower the council's confidence but not raise it. "What changed" ranks every evidence move since the previous receipt by impact; the derivatives gate withholds RYO fields that are not about the token. "What did this decision rest on?" on every receipt removes each input the rules read, one at a time, and shows which ones block, unblock or resize the trade.
- Repeatability (10). Press Verify replay: the decision is rebuilt from the stored evidence and prints
identical: true. Offline:uv run nota replay <id>. Each receipt is also anchored in Bitcoin (OpenTimestamps). - Advanced (5). Practice trades sized from ATR, and closed at whichever of their own stop and target OKX's hourly candles touched first; a twice-daily ledger cycle in CI; every agent scored by Brier against the token's own base rate.
- The spotlight idea, built. The multi-KOL agent reads up to 20 voices (X, Telegram, Bluesky),
finds the tokens they name with sentiment, conviction and urgency, and opens a practice position only when the voices
converge and every user rule passes. Each rule is shown with the value it read and its threshold; the stop comes from
RYO's ATR, and with no RYO evidence there is no trade. Stored runs replay offline:
uv run nota kol-replay <id>. X voices fall back to Tavily search when X refuses, marked "coverage partial".
Track 2 · Dashboards & Interfaces
- Easy to read (25). Open the dashboard: each receipt starts with a five-line summary (now, biggest change, position, what RYO said, next step).
- Sorted by importance (25). "Needs attention" sits on top; "What changed" is sorted by impact; the scorecard puts the next settlements first.
- Works for everyone (10). Keyboard only: j/k, Enter, p, /, ?. Skip links, checked contrast, reduced motion, light and dark, and a Japanese overview.
- The organiser's "Tech Indicator Interface" idea. /indicator: write a rule, get a live validation message pointing at the character at fault, pick an example, preview where it held over the window (chart and bar-by-bar table), then let the tab re-check it every minute or more and log each flip. The monitor is labelled as what it is: a timer in that browser tab, with no notification sent anywhere.
Track 3 · New Skills
- Fills a gap (25).
positioning_check: RYO reports open interest and funding, but some of those fields carry the same value across unrelated tokens. The skill checks RYO's derivatives against OKX for the token and withholds what is not token-specific. - Follows the spec (15). Every skill returns RYO's envelope (
status,data_mode,availability,warnings) at RYO's own path shape:GET /api/skills/,POST /api/skills/{name}/invoke. Try one in the dashboard's "Run a skill". - Fills a gap, the organiser's own idea.
wallet_riskis the "Scam Wallet Detection" build idea: GoPlus flags, the OFAC sanctions list, ScamSniffer's blacklist and Blockscout's record for one address, side by side, with the sources that disagree named. Try it in "Run a skill" with0x098B716B8Aaf21512996dC57EB0615e2383E2f96(the Ronin bridge exploiter: sanctioned, while the explorer still says "ok"). - The organiser's "Tech Indicator" idea.
indicator_checkruns a user-defined condition such asrsi(14) < 30 and close > sma(200)orcrosses_above(ema(12), ema(26))on live closed 1h, 4h or 1d candles (OKX, else Binance) and returns whether it holds, every value it used and where it held over the last bars. The rule is parsed by a hand-written tokenizer and recursive-descent parser, never evaluated as code; a bad rule is a 422 naming the character at fault (nota/skills/indicator_check.py,tests/test_indicator_check.py). - How RYO adopts a skill. Two skills are packaged to lift out in one step:
contrib/positioning_check/andcontrib/move_base_rate/. Copy the folder, thenapp.include_router(router)from itsfastapi_router.py; check it withuv run pytest -q contrib/positioning_check contrib/move_base_rate, which runs offline on recorded answers (the suite refuses the internet). That every skill answers in RYO's envelope is itself tested:tests/test_mcp_server.py::test_the_output_schema_is_the_envelope_every_recorded_ryo_answer_fitsandtests/test_sources_price.py::test_every_skill_speaks_ryos_availability_vocabulary. - Could we use it (20).
contrib/positioning_check/in the repository is a drop-in: no Nota imports, a FastAPI router RYO can include, and its own tests. The same skills are an MCP server at/mcpand an A2A agent, includingverify_receipt, so another agent can check a Nota receipt without a key.
Original here, and common ground
Common ground. Hash-linked receipts, replaying a decision from stored evidence, timestamping it, and scoring forecasts by Brier are established techniques; other entries in this field use them too, and Nota does not claim them as new.
Original here, each with where to check it:
| What | Check it |
|---|---|
It keeps RYO's score. Every day Nota asks RYO about 25 majors and locks every verdict and trade plan
it gives, each lock timestamped in Bitcoin so none can be backdated, then settles them on OKX candles at 24 and 72
hours, every miss counted. Since 2 Oct that is six plans a day: for the other 19, deep_analysis answers
partial with no indicators and so no plan, and each is counted. A call RYO does not answer is counted
as ryo_unavailable, not skipped. |
/scorecard, /api/scorecard.csv, nota/scorecard.py |
| Two public witnesses, checked offline. Bitcoin (OpenTimestamps) and Sigstore's Rekor log; the Rekor signature, inclusion proof and signed timestamp are verified against a pinned key, with no call to Rekor. | uv run nota judge (anchors, rekor), nota/rekor.py, tests/test_rekor.py |
| The proof runs in your browser. Web Crypto hashes the evidence, re-derives the receipt id and reads every citation back; the server's word is not needed. | Dashboard: Verify in this browser;
tests/test_landing_numbers.py |
Seventeen skills in RYO's own envelope, on RYO's /api/skills paths, as an MCP server and over
A2A with an Ed25519-signed Agent Card (price, technicals, positioning, base rates, liquidity, prediction-market odds,
wallet risk, Chainlink and DEX order flow, and more), two of them packaged for RYO to lift out (Track 3). |
/api/skills/, /mcp, Agent Card, contrib/ |
Also here:
- The chain has a vote. Policy v3 reads the Chainlink feed straight from Ethereum (
eth_call, no API in between): RYO's price 2% or more away from it blocks the trade, and so does USDC or USDT off its peg. A long at an MVRV extreme or against DEX order flow is halved. Each check is printed on the trade and can be removed on the receipt to see what it changed. - A council, not one model. Three analysts and a judge, weighted by their own measured Brier scores; code pools them, caps the judge's confidence at the pooled council's, and checks every number in their prose against the evidence.
- Receipts travel. Any receipt embeds in another page as a card (
/r/<id>/embed, oEmbed at/oembed) that links back to its replay, so a call can be quoted anywhere without losing its proof. - It found a defect in RYO's data: one open-interest figure repeated across unrelated tokens, now withheld by a gate.
Limits are listed plainly in LIMITATIONS.md, served here as written in the repository.